Paper
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Tri Dao et al. · arXiv
TL;DR
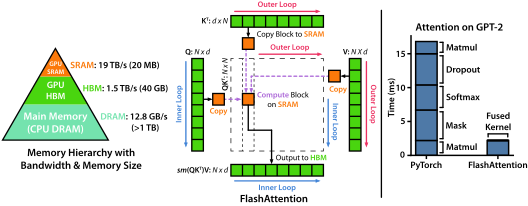
Standard attention is exact but slow on long sequences because it moves a large attention matrix between GPU memory levels. FlashAttention keeps the math exact and reorders the computation so it does more of the work in fast on-chip memory. The result is lower memory traffic and a real wall-clock speedup.
Why it matters
Approximate attention often traded quality for a better complexity class and still failed to run faster on hardware. Dao et al. argued the bottleneck is IO, not just arithmetic. IO-aware exact attention became a default kernel path for training and serving Transformers on long contexts.
Key takeaways
- Self-attention time and memory grow quadratically with sequence length in the standard implementation.
- FlashAttention tiles the computation and avoids materializing the full attention matrix in high-bandwidth memory.
- The algorithm is exact. It is not a sparse or low-rank approximation.
- The paper reports wall-clock speedups, which is the claim approximate methods often missed.