Paper
Attention Is All You Need
Ashish Vaswani et al. · arXiv
TL;DR
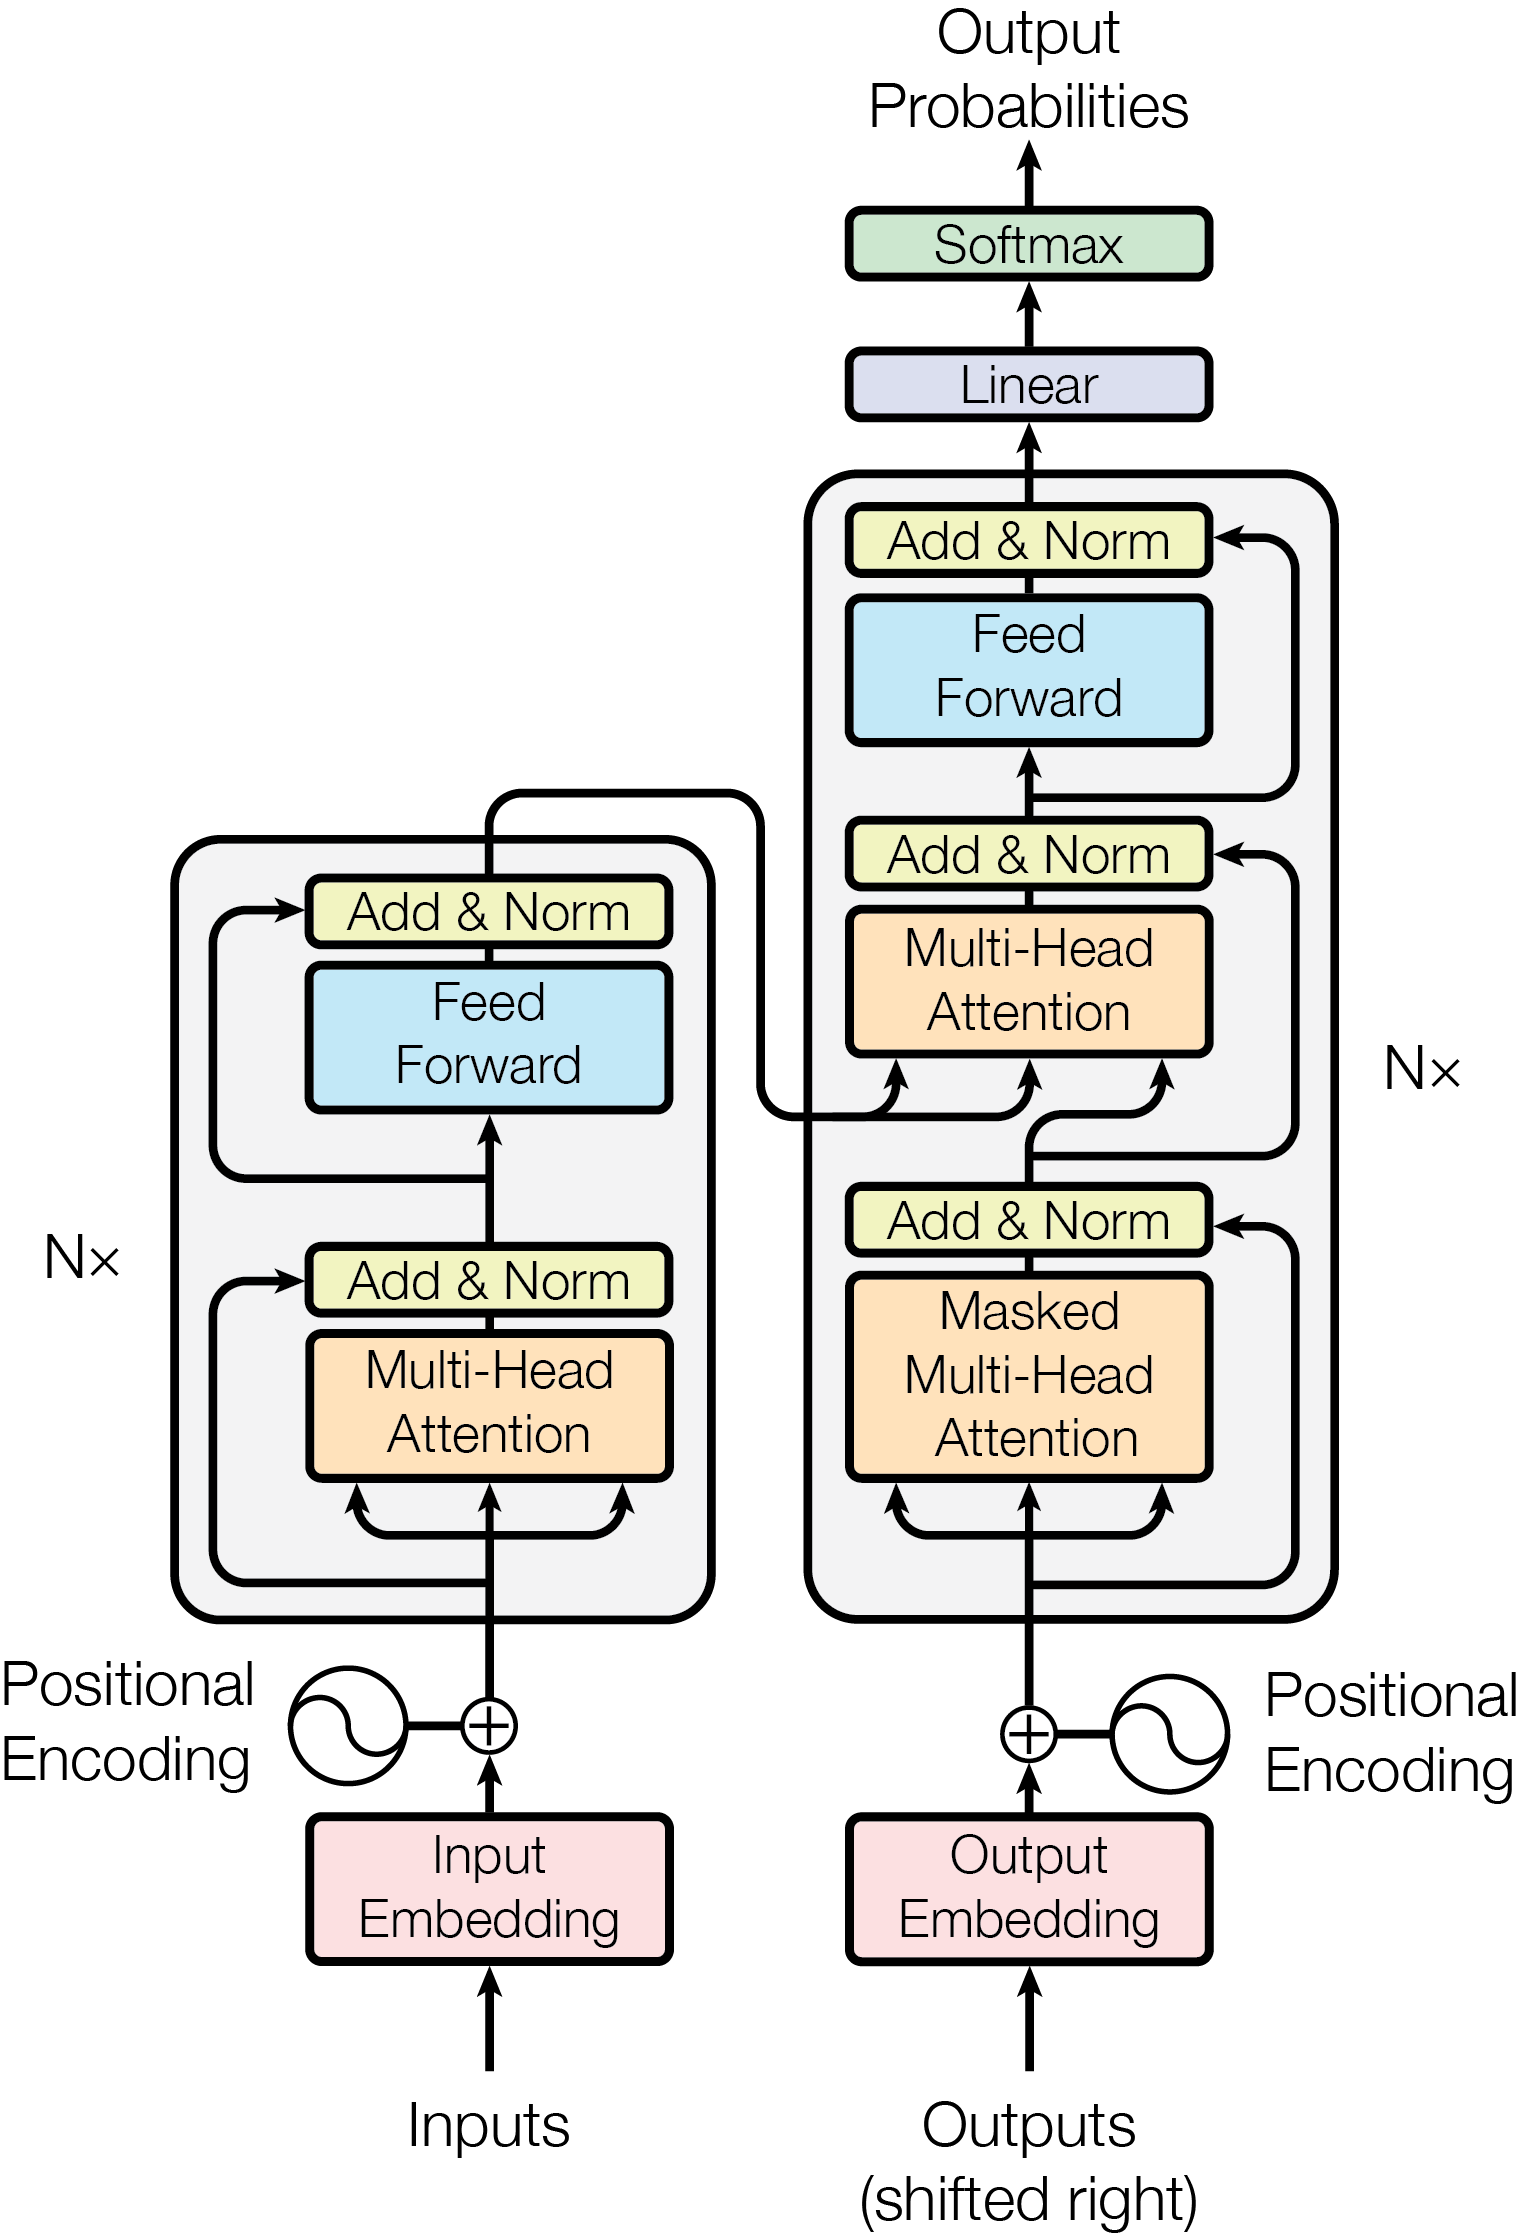
Vaswani et al. introduce the Transformer, a sequence model built only from attention. It drops the recurrent and convolutional layers used by earlier translation models, so tokens in a sequence can be processed in parallel.
Why it matters
Translation models at the time read a sentence one token at a time. That made training slow and long-range dependencies harder to learn. This paper showed an attention-only stack could beat those models on machine translation. The same design later became the base of most large language models.
Key takeaways
- Self-attention lets each token compare itself with every other token in one step.
- Multi-head attention runs several of those comparisons at once, each with a different focus.
- Without recurrence, training can run in parallel across the sequence.
- On English-to-German and English-to-French translation, the model improved quality with less training time than the previous best systems.